Art/Sound/Idea/Vocal/Tract Simulation with Motion Capture
Idea - Vocal Tract Mapping or Simulation to Shape Sound Streams
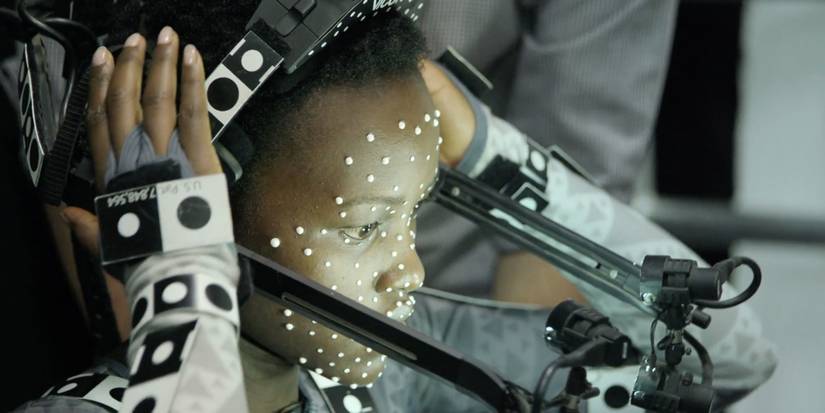
- It's possible today to use motion capture technology to map facial expressions onto a 3-d model of a face. Would a similar technique be able to make it so that a person could, with their own vocal tract, shape any soundstream?
Could we swallow a speaker and a microphone?
- Could it be possible to swallow a speaker and have a microphone on the teeth pick up the result of processing the sounds as played by the speaker and affected by the changes to the vocal tract and the mouth?
Could we simulate this?
- If that's not feasible, might it be possible to do something akin to what autonomous vehicles do when they infer the 3-d structure of the world from a stream of images ... and use a recording of the voice to infer the positions of the vocal elements, and then use that to simulate effects on another audio stream?
- Could we also utilize motion capture on the face as inputs to the simulation's parameters? For example, could we have a bunch of vocal artists come into a recording studio, get mic'd up and geared up with something like motion capture technology, then train a ML model to regress the effect of the face on the voice?
- Would it even be necessary to have motion capture dots on the face today, given how far facial recognition has come? Could we accomplish the same just by using videos of singers?